Book recommendation system
My WGU computer science capstone
Problem
The capstone scenario: readers have trouble finding books that fit their own taste, and bestseller lists and broad ratings ignore individual preference.
Approach
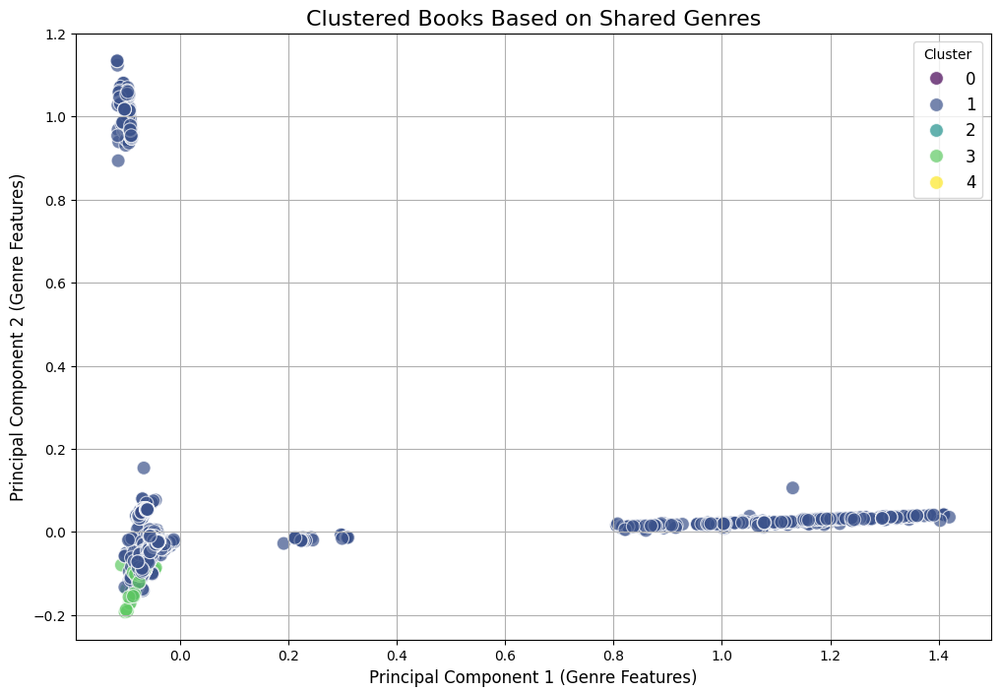
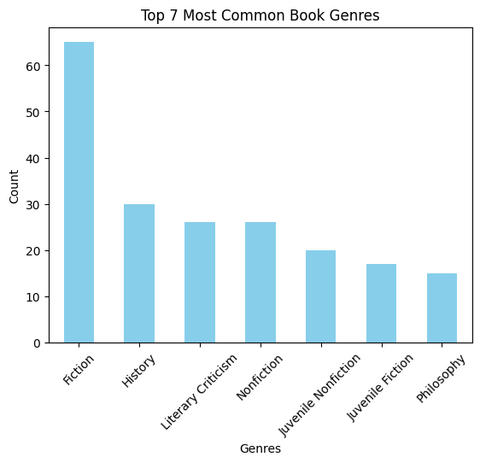
I cleaned and deduplicated the dataset with pandas, combined title, author and genres into one feature string, and vectorized it with TF-IDF. I built a scikit-learn NearestNeighbors model with cosine distance and a cosine-similarity matrix, plus a similarity function weighted by genre and author. I explored the data in a Colab notebook: top genres, the rating distribution, ratings against review counts, and KMeans genre clusters projected with PCA. The written deliverable covered a proposal, an executive summary, a post-implementation report and a quick-start guide.
Process
3 dated steps, from the project’s history
-
Proposal
The capstone proposal letter, written for WGU's role-play scenario.
-
Code and notebook
Uploaded the app, the exploration notebook, the capstone document and requirements.
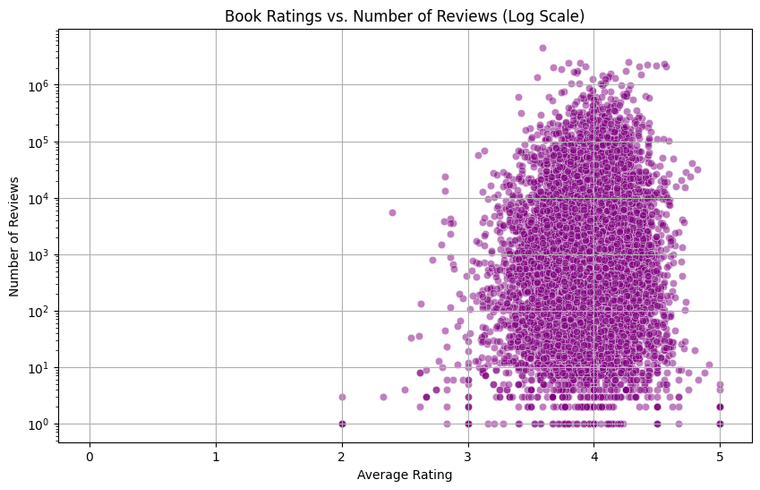
Exploration: average rating against review count. -
Portfolio polish
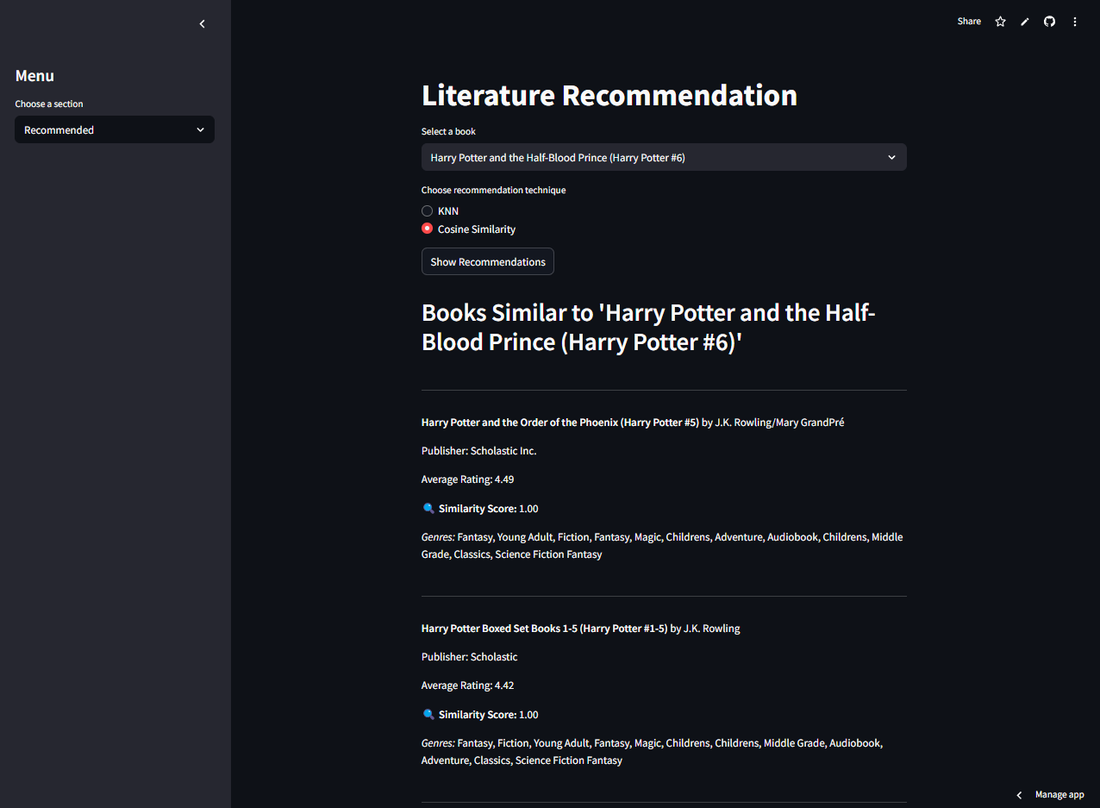
Added a dev container, refactored the model, popular and recommended modules, and captured the app. See Fig. 1, above.
Results
The testing in my report supports the idea that metadata-based recommendations beat popularity-based ones, with a caveat I wrote into the report: "accuracy" here is subjective, and similarity scores run high for books in a series.
Lesson
Content-based filtering does very well on series and under-scores standalone books, and the report says so.